The context nobody reviewed: what reaches the model beyond your prompt
Context engineering for AI agents: tool results, memory and retrieved text the team never reviewed, why they cause failures and cost, and what to change.
When an AI agent that worked in testing starts making mistakes in use, the team cannot change the model, but it controls everything sent to it.
The agent started simple, answering customer questions about orders with one page of instructions and a single tool to look them up. It passed every test the team wrote for it.
Over the following months it gained tools to track deliveries and issue refunds. Retrieval came next, adding passages from the company's policy documents to relevant requests. Then came sessions long enough to handle a whole complaint, and finally a long-term memory of what each customer had asked before.
Somewhere along the way, the agent started losing track of instructions halfway through long conversations, calling the refund tool when a customer only asked where a parcel was, and costing more every month. No single client's AI system looks exactly like this one, but we have watched custom agents we built at Vstorm decline the same way, as tools and memory piled up faster than anyone tested them.
Each time, the team's first rescue was a new instruction, and early on that was the right call. A line telling the agent to check the delivery status before it considers a refund is the cheapest fix there is, and it often deals with the failure someone reported.
Each new line helped for a shorter time than the one before. Drew Breunig describes where this habit leads: a prompt grown one fix at a time until it is "barely legible to you, and it's downright impenetrable to your colleagues."
The rescue starts with what the model received #
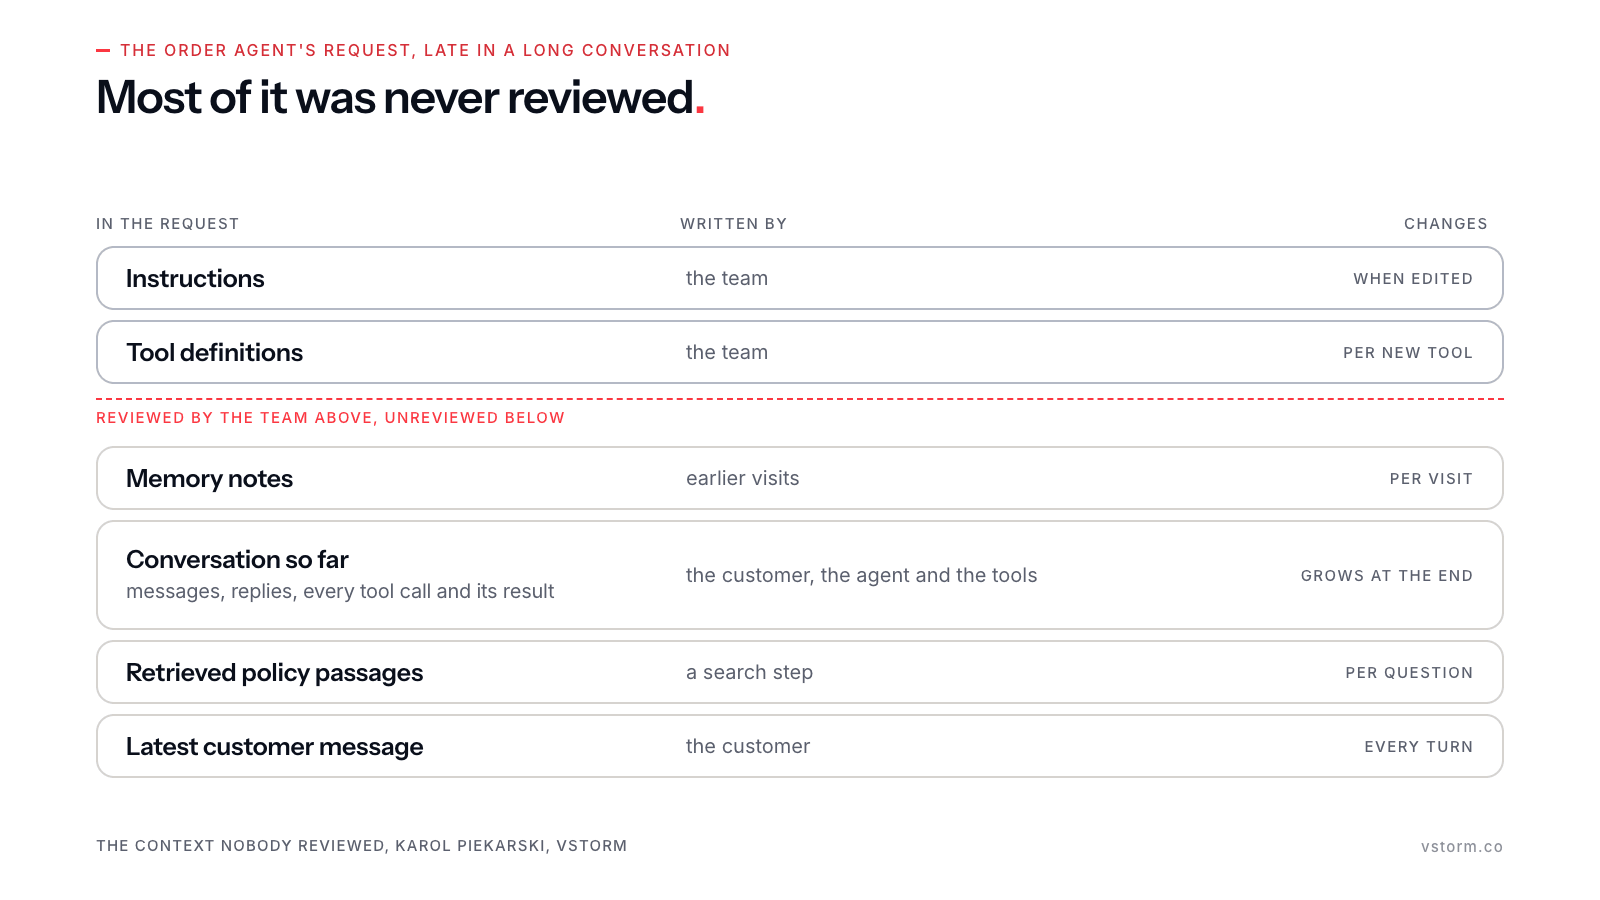
The rewrites helped less each time because the failures were starting outside the instructions. Every capability the agent gained added text to the request while it ran: tool results, retrieved documents, conversation history, and memory notes. Each tool result stayed there for every step that followed. The team had reviewed only the instructions and the tool definitions.
The team's tracing tool recorded all of it, but after a bad answer, the engineers read the answer and the instructions and skipped the tool results in between. The agent needed an engineer who reviewed what entered the request and read the whole of it when a run went wrong.
Context engineering, the work of deciding what enters that request, is mostly subtraction. Anthropic, which sells Claude, describes the goal of effective context engineering as "finding the smallest possible set of high-signal tokens that maximize the likelihood of some desired outcome." Every fix the order agent's team had made so far added text to the request.
The rescue changed course when the order agent's team stopped editing the instructions and read a whole request instead. They took a conversation in which the agent had offered a refund on an order that had already shipped, opened the request behind the bad answer in their tracing tool, and read it from top to bottom. The instructions were there, intact.
Further down sat a status the tracking tool had returned early in the conversation, while the order was still waiting for stock. By the time the customer asked again, the parcel was on its way, but the old status was still in the request, and the agent had answered from it.
The line had been in the logs since the first bad answer. Nobody on the team had written or reviewed it, because the tracking tool had put it there while the agent ran. Injecting the current order state on every turn makes an answer like this less likely, but the old tool result stays in the request, contradicting the new state, until something removes or marks it.
The line that matters runs between content someone reviewed for this agent and content that reached the model without anyone looking at it. Instruction files and skills, the packaged instructions that agents such as Claude Code load when a task seems to match them, are written by people, but they also load at run time, and a skill added for one task can arrive in a request it was never checked against.
Wrong picks and outdated results do more harm than length #
The wrong refund calls started when the new tools arrived, and the evidence points at choice more than size. Hongwen Song and Song Wei measured agents against skill libraries of increasing size and found performance falls "by up to 21% when scaling from a small set of helpful skills to a 202-skill library." Up to 68% of that loss came from the agent picking the wrong skill, while the effect of the extra text in the request stayed "small and indistinguishable from zero."
They tested two Claude models. Anthropic says in its documentation that Claude's ability to pick the right tool "degrades once you exceed 30–50 available tools." Each addition changes how the agent behaves on tasks it already handled, so it needs testing as a change to the whole agent.
In our experience, each new generation of frontier models picks tools more reliably, but the most capable model is rarely the right one for a production agent. For a task as frequent as order questions, cost and response time per answer matter as much as accuracy, so the right choice is usually the cheapest, fastest model that does the task well enough. That model gains the most from a clean request.
Mohsen Arjmandi found that when a filter kept only the relevant context, by design, two smaller Claude models held their scores or improved, significantly so on one of the two benchmarks, while the largest models, Opus 4.7 and GPT-5.5, were already at their ceiling with everything left in. Whether an agent should retrieve documents at all or load them into a long context window is a separate decision, covered in our post on RAG and context engineering.
Stale content does a different kind of damage. Microsoft researchers tested an agent that itemizes expenses in Dynamics 365, the business software their company sells, where a single tool response could run to 3,000 tokens.
When the agent kept every tool result in its request, it completed 71.0% of its tasks. When it kept only the last five tool calls and their results, plus a summary of what came before, it completed 91.6%, and among its failed runs, errors caused by out-of-date state fell from 34 to 4.
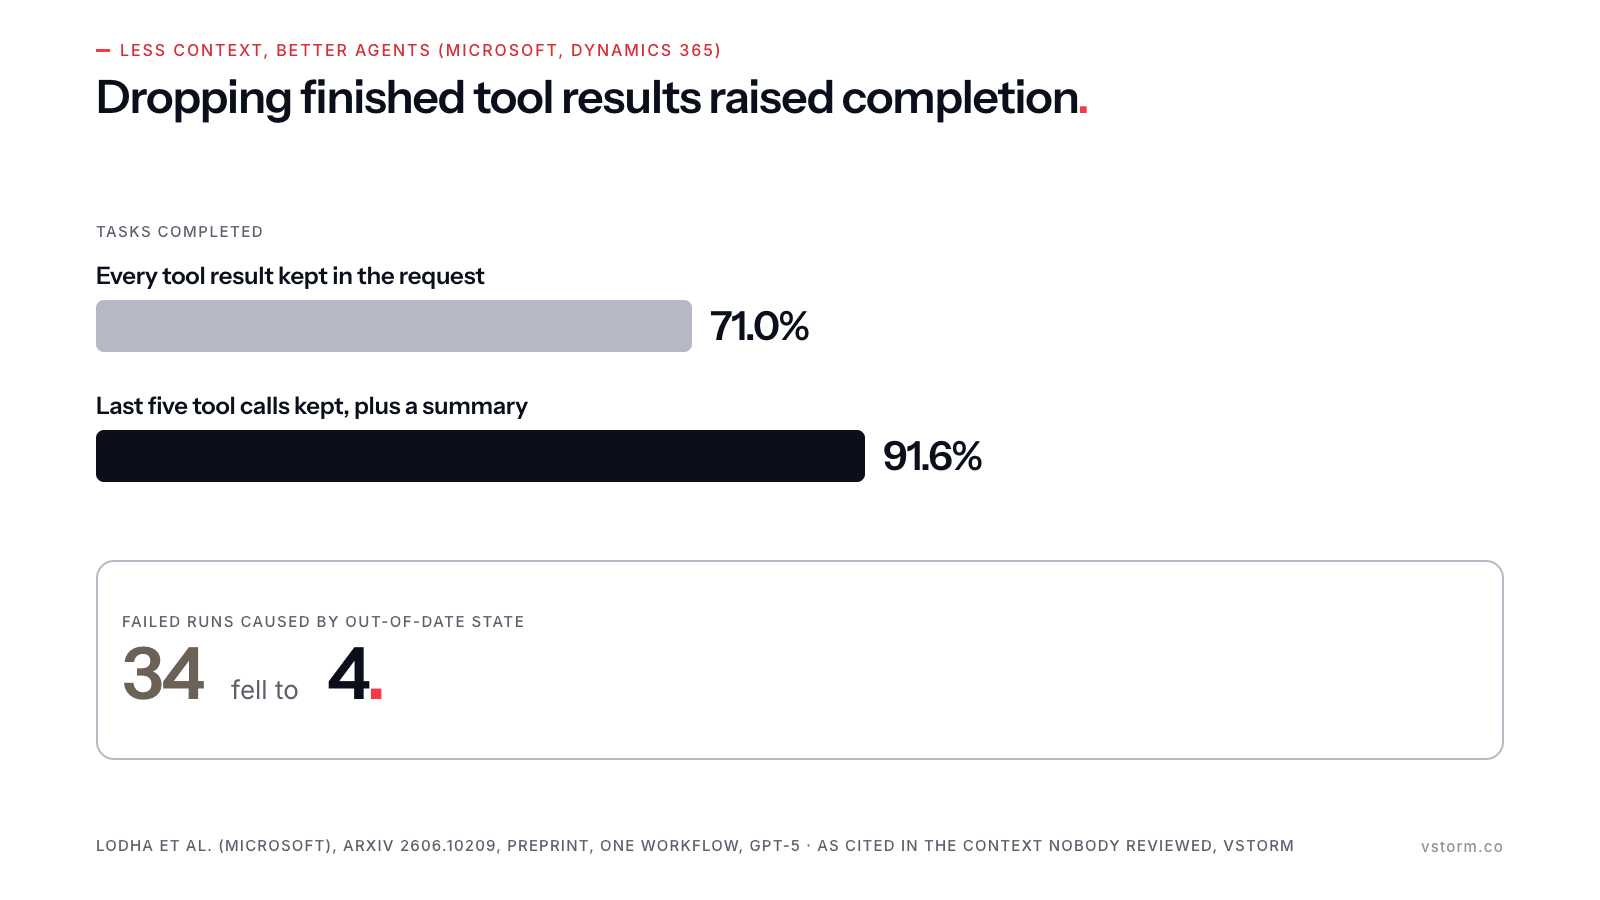
The authors conclude that "older context can be actively detrimental rather than merely redundant." The preprint covers one workflow and one main model, GPT-5, but its failure matches the order agent's: an old result still in the request can look to the model like a current fact.
Removing old content is not safe by default either. Louis-François Bouchard and colleagues at Towards AI, which sells AI engineering courses and consulting, tested compaction on their own course tutor. Compaction replaces older turns of a conversation with a summary to save space.
In their probes, the compacting setups lost facts planted earlier in the conversation, while the full history answered correctly from contexts of 363,000 to 879,000 tokens, the units of text a model reads and is billed by. "A bigger context was not the problem. Rewriting it was."
The compacting production setup also "paid roughly twice as much" per turn as the full history. The tests were small, with one or two trials per setting, and the authors call the exact percentages noisy.
Set beside the Microsoft study, they show why no general rule settles what to keep. Dropping finished tool results helped one agent, and summarizing a conversation the student was still relying on hurt another. Someone has to decide, for each kind of content, how long it stays and in what form, and test that decision on real tasks.
Errors in unread content get blamed on the model #
Memory is the hardest of these to see. Its notes enter the request on later visits, long after the conversation that wrote them, so a wrong note surfaces as an answer that looks like the model's own mistake. In the order agent, a note that a customer once accepted a refund instead of a replacement could steer every later conversation with that customer, and anyone reading the transcript would see only the model choosing badly.
Researchers from three US universities planted harmful notes in an agent's memory until 64 of them had each caused a failure, then tested standard methods that read the agent's logs to find the cause. One blamed the model in all 64 cases and never the planted note; the other two did no better than a coin flip or gave no answer.
Graders can miss the same failures. In the Towards AI tests, a blind judge rated the tutor's answer good "100% of the time" on the turns where the tutor "had demonstrably lost the planted fact."
Even the company that builds the model can miss a fault in this layer. Anthropic reported a caching change that, in sessions idle for over an hour, cleared the model's earlier reasoning from Claude Code's context, and a bug then repeated the clearing on every later turn. The change passed code reviews, unit and end-to-end tests, and internal use, and "it took us over a week to discover and confirm the root cause."
A shorter request can cost more #
In the Microsoft study, input made up more than 99.7% of all tokens, because an agent sends its whole request again at every step. Prompt caching changes the price of that repetition. The provider stores the processed start of a request, and a later request that begins the same way pays less for it.
As of October 2026, a cache read costs 0.1 times the normal input price on most Anthropic models, and as little as 0.025 times on the newest ones. A five-minute cache write costs 1.25 times.
The discount holds only while the start of the request stays the same, and only for a few minutes. In Maxim Khailo's measurements, an Anthropic cache left idle was still there after 5 minutes and gone after 10, in all 48 samples taken at the 10-minute gap, so a customer who pauses mid-conversation can make the next request pay to rebuild it.
Anthropic's documentation warns that "Modifying tool definitions (names, descriptions, parameters) invalidates the entire cache," and any content that changes near the top of the request makes everything after it miss the cache. Those tokens are then billed at the full input price, or written to the cache again at the higher write price.
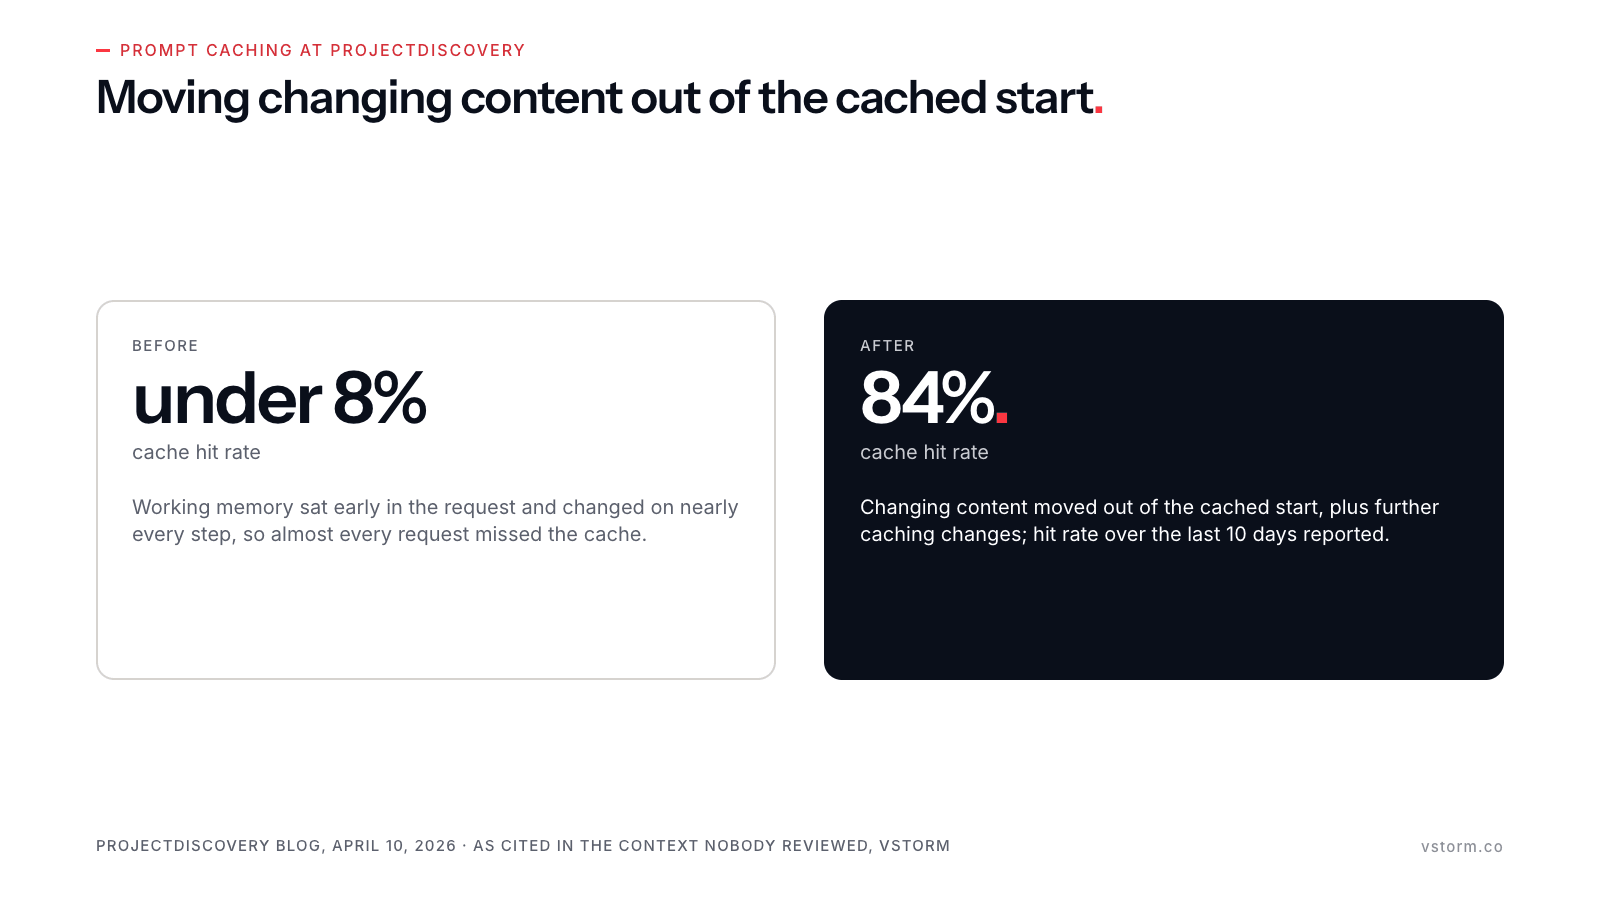
ProjectDiscovery, which sells security tooling and runs its own agent, Neo, found this out from its bill. The agent's working memory sat early in the request, and as the team wrote, "Working memory changes on nearly every step. This was silently killing our cache hits."
The hit rate was under 8%. After the team moved the changing content out of the cached start and made further caching changes, the hit rate reached 84% over the last 10 days they reported.
Pruning runs into the same rule. Dropping an old tool result changes the request from that point on, so on the next step everything after the cut misses the cache.
Fewer tokens do not guarantee a smaller bill. Researchers at PointFive, which sells a cloud cost management platform and a token-optimization product, found in a preprint that their largest compression setup "reduced delivered tool-output tokens by 38.4% but increased billed cost by 6.8%." They conclude that optimization should be judged by "cost per successful task."
What to change before the next rewrite #
An agent with a few tools, short sessions, and no memory needs little of what follows. Its request is still mostly the instructions the team wrote, so rewriting them is the right fix. For an agent that gathers content while it runs, we recommend three changes before anyone edits the instructions again:
- Read the full request of a bad run next to a good one. When the agent gets a task wrong, open the complete text it sent to the model, tool results and memory included, and put it beside the request from a run that got the same task right. Read the differences before changing anything. Instrumentation that follows OpenTelemetry's draft conventions does not record the full text by default. If yours does not, turn that on first.
- Have an engineer review every change to what enters the request. The request is assembled by code: the prompt template, the tool list, the retrieval settings, the memory rules, and whatever trims old results. No new tool, skill, data source, or memory feature should reach production without that review.
- Order the request by how often each part changes. Instructions and tool definitions go first, then anything fixed for the whole conversation, such as memory notes loaded at the start. The conversation follows and grows only at its end. Anything that changes on every question, such as retrieved passages or working memory, goes last. Prune old tool results in occasional batches, so the cache is rebuilt once instead of on every turn. Track the cache hit rate with latency and errors.
When you read a bad run's request, the symptom tells you where to look first:
| Symptom | Where to look in the request | What to look for |
|---|---|---|
| The agent calls the wrong tool | Tool definitions and loaded skills | Two tools or skills that match the same request, or dozens to choose from |
| It answers from outdated facts | Earlier tool results, memory notes, and retrieved passages | A status, note, or passage older than the latest change |
| It loses instructions in long sessions | Conversation history and any summary of it | Instructions buried under many turns, or dropped by a summary |
| The bill rises without more traffic | The number of tokens in each request, and anything that changes between steps | Requests that grew, more steps per task, the first point where two consecutive requests differ, or pauses longer than the cache lasts |
Before approving any addition, run it on a fixed set of tasks the agent already handles and compare the success rate and the cost per successful task before and after.
Sources #
- Drew Breunig, "The Problem is Prompt Debt," dbreunig.com, June 22, 2026.
- Anthropic, "Effective context engineering for AI agents," Anthropic Engineering, September 29, 2025, accessed October 2026.
- Hongwen Song and Song Wei, "More Skills, Worse Agents? Skill Shadowing Degrades Performance When Expanding Skill Libraries," arXiv 2605.24050, version 2, June 23, 2026. Preprint.
- Anthropic, "Tool search tool," Claude Platform documentation, accessed October 9, 2026.
- Mohsen Arjmandi, "Distractor-Aware Truncation: Disentangling Context-Length Effects from Signal Loss in Long-Context LLM Benchmarks," arXiv 2608.03297, August 4, 2026. Preprint.
- Lodha, Varnosfaderani, Chakraborty, and Mithal (Microsoft), "Less Context, Better Agents: Efficient Context Engineering for Long-Horizon Tool-Using LLM Agents," arXiv 2606.10209, June 8, 2026. Preprint.
- Louis-François Bouchard, with Omar Solano and Samridhi Vaid, "Context Engineering in 2026: Why We Stopped Compacting Our Agent's Context," Towards AI, August 18, 2026.
- Tanzim Ahad et al., "The Misattribution Gap: When Memory Poisoning Looks Like Model Failure in Agentic AI Systems," arXiv 2605.22842, May 12, 2026. Preprint.
- Anthropic, "An update on recent Claude Code quality reports," Anthropic Engineering, April 23, 2026.
- Maxim Khailo, "Your Agentic Workflow's Cache Keepalive Costs 8x Too Much," blog.mempko.com, July 21, 2026, updated August 6, 2026.
- Anthropic, "Prompt caching," Claude Platform documentation, accessed October 9, 2026.
- Parth Malhotra, "How We Cut LLM Costs by 59% With Prompt Caching," ProjectDiscovery Blog, April 10, 2026.
- Sarel Weinberger and Amir Hozez (PointFive), "Token Reduction Is Not Cost Reduction," arXiv 2607.12161, version 5, August 12, 2026. Preprint.
- OpenTelemetry, "Semantic conventions for generative client AI spans," status Development, accessed October 13, 2026.